News, Breakthroughs & Recognition
Belfort pushes the boundaries of encrypted computation. This page shares our latest milestones, recognition, customer stories, and insights.
Live insights & milestones
Stay up to date with our latest announcements, product developments, industry recognition, and expert insights in secure, large-scale encrypted computation.
San Francisco / Leuven — 7 October, 2026. Belfort today released a hotword detection model that runs end to end on encrypted audio. Hotword models are the ones that listen for phrases like “OK Google” or “Hey Siri”. Built with Belfort’s upcoming eML platform, which combines Google's HEIR compiler with Belfort's GPU library, it is now available to try at hotword.belfortlabs.com.
Listening Without Hearing
In 2019, Time reported that thousands of Amazon employees were reviewing Echo recordings, including clips captured when the device mistakenly thought it had heard its hotword, “Alexa”. More recently, reporting on Meta's Ray-Ban glasses described footage reviewed by people working for Meta, some of it capturing deeply private moments.
The privacy risks behind personal assistants are growing quickly. Tools such as Wispr Flow have made dictation a default way of writing, and Granola sits in meetings that were never previously recorded at all. What flows through these systems is no longer "play some music" but salary conversations, client calls and product decisions, which is why privacy and security are becoming a major concern.
Encrypted computing removes the need to decrypt entirely. Audio is encrypted on the device, the hotword check runs on the encrypted signal, and only you can see the result. The server does the work but never hears a word.
Try It: Guess the Word
To show it working, we built a game. Players see a set of hints and have to guess three hidden words, speaking each guess aloud. The model listens under encryption and confirms when a player lands on one, but since the audio is encrypted before it leaves the browser, the server never learns what was said.
The game is simple, but it sets a higher bar than a benchmark. If the round trip doesn't feel instant, nobody plays. Hitting that bar was only possible because of our toolchain. Combining Google HEIR with Belfort's GPU acceleration library in a single platform let us build and iterate on this without hand-writing the cryptography.
Players who want full control can also generate their own keys in the browser. Thanks to state-of-the-art key compression, the public key material comes to about 1.2 GB, small enough to upload in a few minutes even on a slow connection.
Nothing in this stack is specific to audio. Encrypted computing works on the math underneath the data, not on what the data means, so the same approach applies to images, time series, text and tabular data.
"Hotword detection is the smallest piece of a voice pipeline, but it's the one that has to respond instantly. That's why we started there: if encryption can keep up with the hotword, it can keep up with everything that comes after. A year ago, this meant writing the cryptography by hand and hoping it would run fast enough. Today our platform handles that for us, so we can move on to the larger models next."
"If encryption can keep up with the hotword, it can keep up with everything that comes after."
— Michiel Van Beirendonck, CTO, Belfort
What's next
Hotword detection is one model in a broader effort to make encrypted computing practical rather than theoretical. Next is our full pipeline, which will let developers bring their own models and deploy them under encryption without cryptography expertise. Our first release supports convolutional neural networks, a widely used class of models, and we'll expand to larger and more complex models from there. Speed was never the only bottleneck. Using encrypted computing has always required a specialist, and that's what we want to change.
Belfort’s eML platform is currently in alpha with early partners. Organizations interested in running their own models and data under encryption can join the waitlist at eml.belfortlabs.com.
About Belfort
At Belfort, we believe that in an AI-first world, trust is all you need and the future of computing is encrypted. Belfort enables that vision by accelerating Encrypted Compute to make it practical at scale, ensuring that sensitive data can be processed without ever being decrypted. A spin-off from KU Leuven’s world-renowned COSIC lab, Belfort combines breakthroughs in hardware and algorithms to build the next layer of secure computing. The company has offices in San Francisco, USA, and Leuven, Belgium. https://belfortlabs.com/
Encrypted hotword detection
Belfort releases hotword detection that runs on encrypted audio
What if a recommendation engine could know exactly what to show you, without knowing anything about you? Research from LG Electronics' Emerging Technology Lab, together with NYU and Belfort, brings that closer than most people expect. New LG-NYU algorithms cut encrypted embedding lookups by 56x, but reaching near real-time speed took Belfort's GPU acceleration platform, which delivered a further 400x speedup and brought recommendation latency down to 0.56 seconds, from nearly four minutes. User data is never decrypted and nothing is exposed to the server, so personalization no longer has to come at the cost of privacy.
Recommendations That Learn Nothing About You
Every day, companies collect more data about what you buy, watch, and click. That data is what makes a recommendation feel useful instead of random. But that same data is also deeply private, and regulators across Europe and beyond keep tightening the rules on how far advertisers can reach into a person's life. The old trade-off was uncomfortable: better recommendations meant handing over more of your personal information.
Researchers at LG Electronics, Emerging Technology Lab, have been exploring how privacy-preserving technologies can enable personalized advertising recommendations while maintaining strong privacy guarantees. As part of an ongoing research effort, the team, in collaboration with NYU, developed new algorithmic techniques for encrypted recommendation inference and partnered with Belfort to evaluate how hardware acceleration could make these approaches more practical.
In this post, we discuss how LG-NYU’s encrypted recommendation algorithms were combined with Belfort's acceleration platform, the resulting performance improvements, and what this means for the future of privacy-preserving AI.
The Challenge: Recommendations Without Invading Privacy
A recommendation engine learns from your behaviour. Feed it enough signals about your persona, such as age, browsing history, location, and your activities, and it gets good at making personalized recommendations. The catch is that those signals sit on a server, readable by the company that holds them and exposed to anyone who breaches it.
Encrypted computing or Fully Homomorphic Encryption (FHE) changes the rules. It lets a server compute directly on encrypted data without ever decrypting it. The user encrypts their information before it leaves their device. The server produces a recommendation on data it cannot read. The encrypted answer comes back, and only the user can unlock it. The company serves a relevant recommendation and learns nothing about the person it served, not their age, nor their browsing history nor their location.
For years FHE was treated as a beautiful idea that was far too slow to use. The work with LG Electronics and NYU was about proving that is no longer true.
Why Recommendation Models Are Hard to Encrypt
To see the difficulty, it helps to know what a recommendation model does under the hood.
A canonical architecture is the Deep Learning Recommendation Model, or DLRM, which Meta open-sourced in 2019.
It handles two kinds of input. Dense features are plain numbers, like the time of day or how often you visit. Sparse features are categories, like a product ID or a country, and each one can have tens of thousands of possible values.
A model cannot use a category directly, because its ID is a name, not a number you can do math on. Product four million is not "twice" product two million; the IDs are arbitrary, so the model needs a different representation. To work around this, the model keeps an embedding table: a large lookup table where every category has its own row of learned numbers describing how that category behaves. The model looks up the right row for each sparse feature, runs the dense features through a small neural network, and combines everything to predict how likely you are to click.
The embedding lookup is what makes encryption painful. On normal data, grabbing one row is instant; the server jumps to it and ignores the rest. Under encryption the server is not allowed to know which row you want, because the row index is itself private and would reveal some information to the server. The only way to select a row blindly is to run encrypted math against every row in the table and let the arithmetic cancel out all but the one you asked for. Retrieving a single row means touching all of them and that is the bottleneck.
Algorithmic Optimizations: Faster in Software
The first gains came from being smarter about that lookup, before any specialised hardware enters the picture.
To achieve a more optimal outcome, LG Electronics research team, in collaboration with Prof. Reagan’s team at NYU, used a technique called client-side digit decomposition. Instead of representing the desired row as one enormous selector spanning millions of entries, the client splits the index into a few small pieces, the way the number 4,839,201 is really a handful of digits rather than one impossibly large symbol. Each piece needs only a small selector, and the server recombines the pieces to reconstruct the correct row. Because the pieces are small, the volume of encrypted multiplication collapses, giving a 56x speedup over the previous state of the art for encrypted embedding lookups.
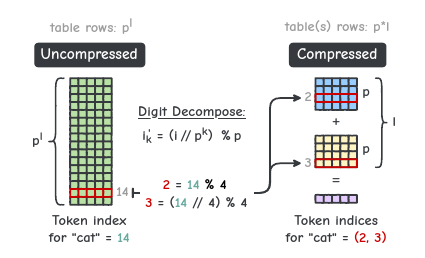
A second technique, called multi-embedding packing, processes several embedding tables at once instead of one after another, so each expensive encrypted operation does more useful work.
Together, these techniques significantly reduce the computational burden traditionally associated with FHE-based recommendation systems.
Hardware Acceleration: Closing the Gap to Real Time
Software gets you part of the way and while LG and NYU’s algorithmic optimizations dramatically reduced the amount of encrypted computation required, achieving practical latency required additional acceleration at the systems level. The rest comes from the hardware underneath.
Belfort specifically designed GPU acceleration to accelerate the operations underlying the private recommendation system by LG-NYU. Therein lie two complexities: (i) offering the same functionality as the pure software version, (ii) improving the performance of software version with hardware acceleration. Using Belfort’s compiler toolchain, which builds on Google's open-source HEIR compiler, the results are almost instantaneous. We achieve a 400x speed-up, bringing the latency of a recommendation down to 0.56s. Without acceleration, this would have taken nearly four minutes to execute.
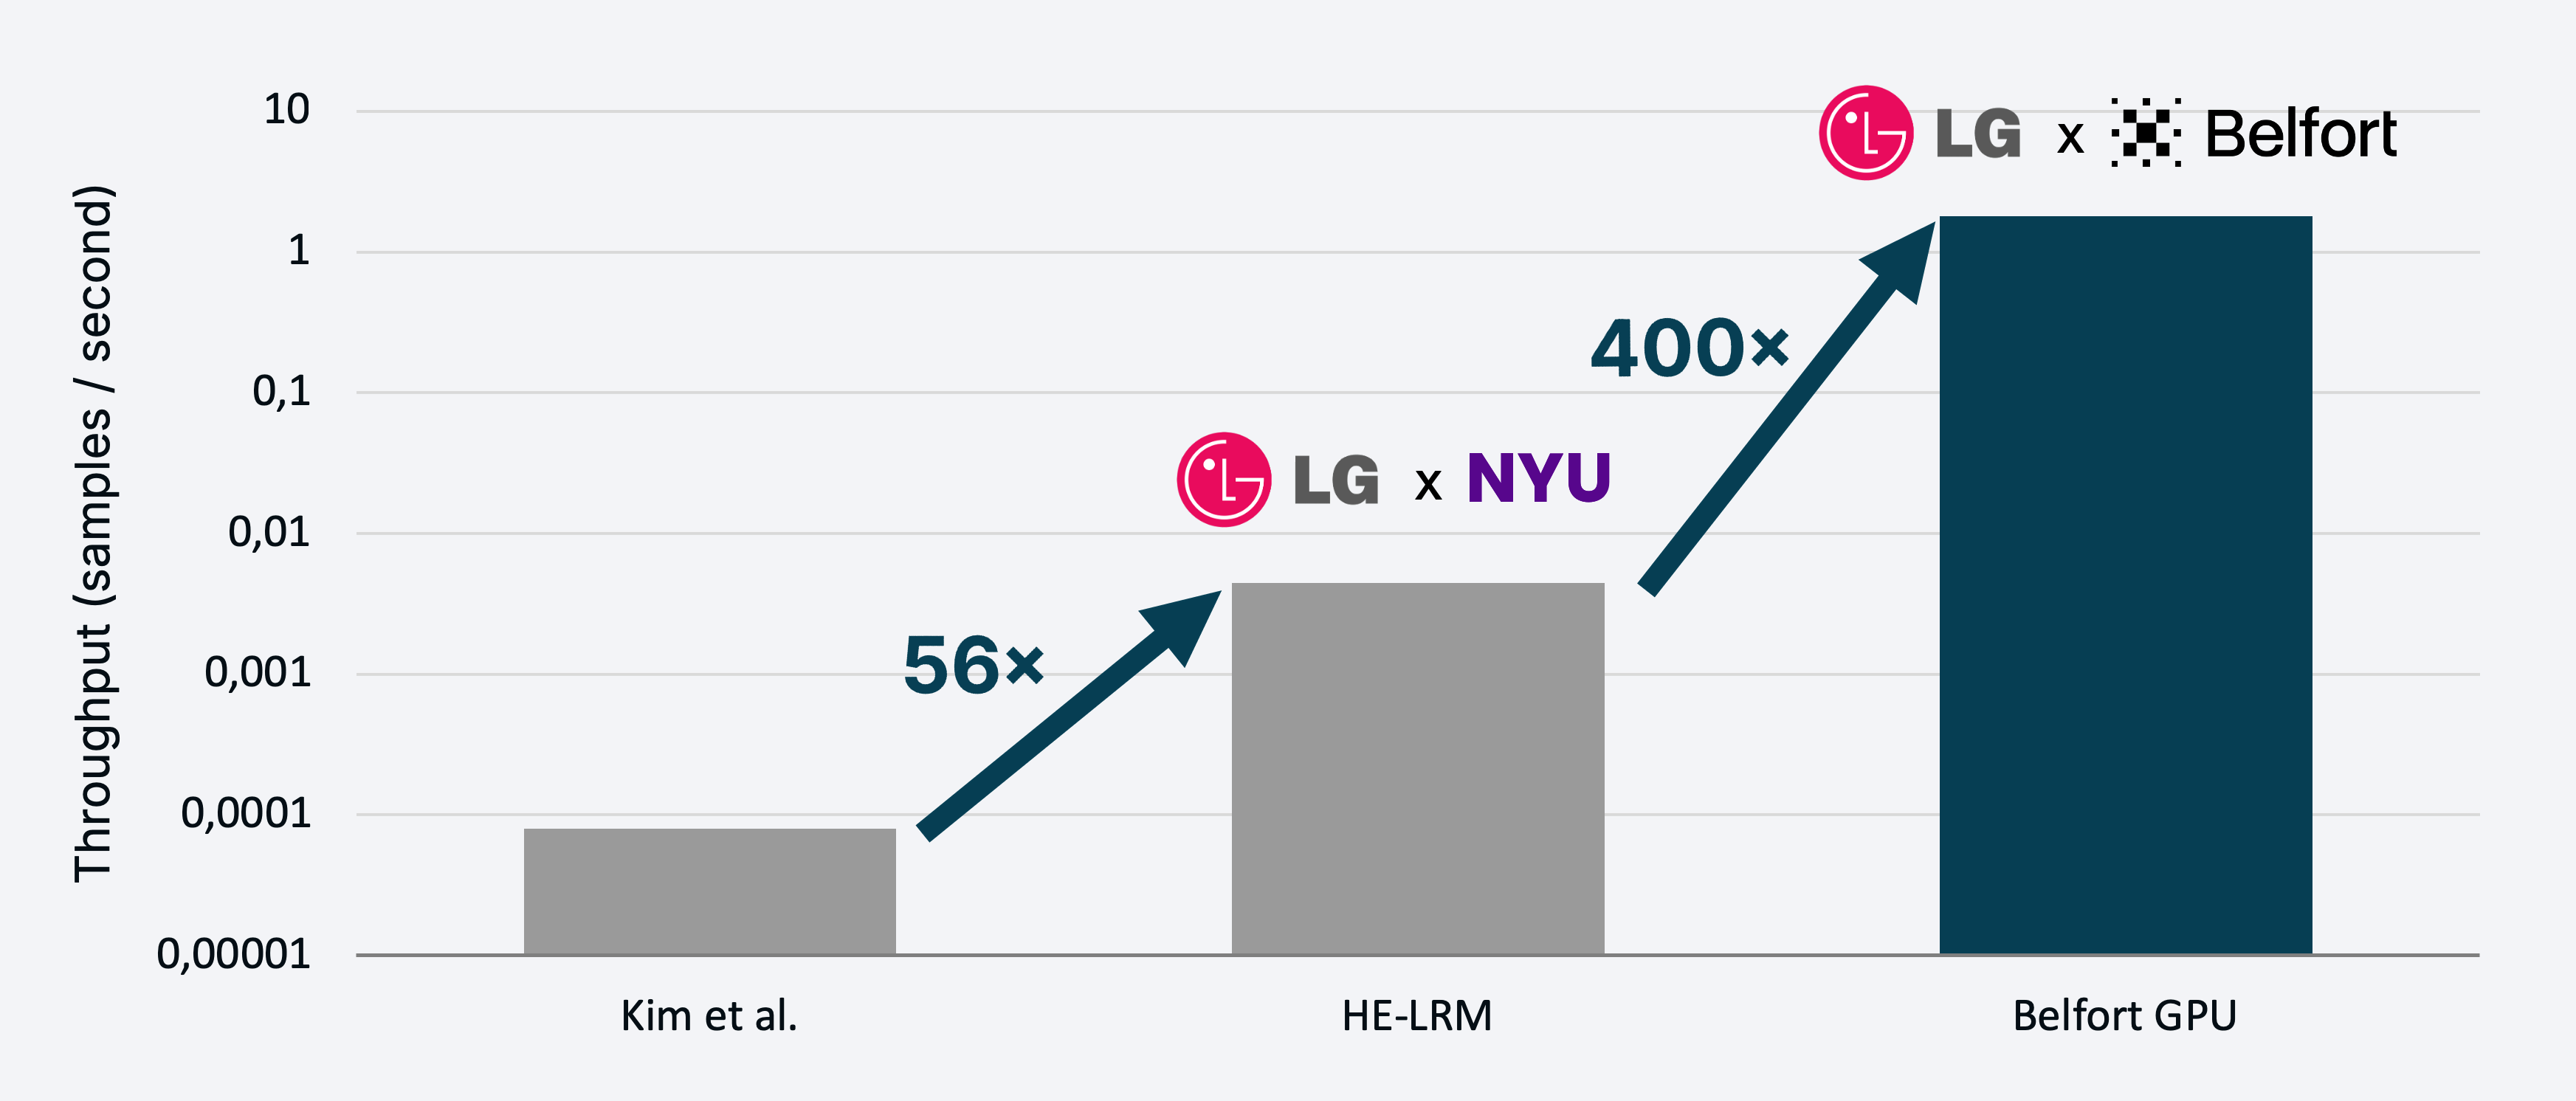
An advantage of using a compiler instead of fully optimizing the model is that improvements in the underlying building blocks translate directly into improved performance for every model. This means that Belfort will continue to support more and more models with faster and faster performance.
What This Means for Advertising Institutions
At sub-second latency, encrypted recommendations are moving closer to being operationally viable. User data can be scored against a model without ever being decrypted, removing the exposure window that today's systems all share. No need to trust the cloud provider, the hardware, or the administrator. Trust the mathematics.
This matters beyond LG Electronics. Any company that personalises against sensitive user data, whether a platform, a publisher, or an advertiser working across jurisdictions, faces the same tension between recommendation quality and privacy. An advertiser can show a regulator that user data was never exposed, because mathematically it never was. Personalisation becomes a privacy feature rather than a liability, and the compliance story and the product story start pointing the same way.
Jacob Song, Head of LG Emerging Technology Lab, chimes in: "Our research team had already demonstrated significant algorithmic gains for encrypted recommendation inference. What impressed us was how quickly Belfort's acceleration platform translated those advances into practical execution times. The combination moved encrypted recommendation from an interesting research result toward something that could realistically be evaluated for future applications."
Belfort’s acceleration translated our algorithmic breakthroughs into practical execution times, with a real path to production.
— Jacob Song, Head of LG Emerging Technology Lab
What's Next
Now is the right time to start building with FHE. The performance barriers that made it impractical are coming down faster than most people expect. GPU acceleration continues to drive latency down and Belfort’s compiler workflow keeps widening so more model architectures can be run on encrypted data with less hand-tuning than was previously necessary.
Research Project Notice
This work was conducted by LG Electronics research team, as part of an exploratory research initiative focused on privacy-preserving machine learning. The system described here represents a research prototype intended to evaluate the feasibility of encrypted recommendation inference and is not currently deployed as a commercial service for LG customers or integrated into broader LG business-unit offerings.
Further Reading
This work builds on research on encrypted recommendation models. See "HE-LRM: Efficient Private Embedding Lookups for Neural Inference Using Fully Homomorphic Encryption" by Karthik Garimella, Austin Ebel, Gabrielle De Micheli, and Brandon Reagen, which introduces the embedding compression technique behind the software speedup. The implementation builds on the open-source Orion FHE compiler framework from the NYU research group.
About Belfort
At Belfort, we believe that in an AI-first world, trust is all you need and the future of computing is encrypted. Belfort enables that vision by accelerating Encrypted Compute to make it practical at scale, ensuring that sensitive data can be processed without ever being decrypted. A spin-off from KU Leuven’s world-renowned COSIC lab, Belfort combines breakthroughs in hardware and algorithms to build the next layer of secure computing. The company has offices in San Francisco, USA, and Leuven, Belgium. https://belfortlabs.com/
Encrypted advertising recommendations
What if a recommendation engine could know exactly what to show you, without knowing anything about you?
San Francisco / Leuven,July 16, 2026 — Belfort today released the "so far" CIFAR demo, an encrypted implementation of ResNet-20, a popular model for image classification. It outperforms recent SOTA by 3x with a total latency of less than 200ms. A public demonstration is available at sofar.belfortlabs.cloud.
The AlexNet Moment For Encrypted AI
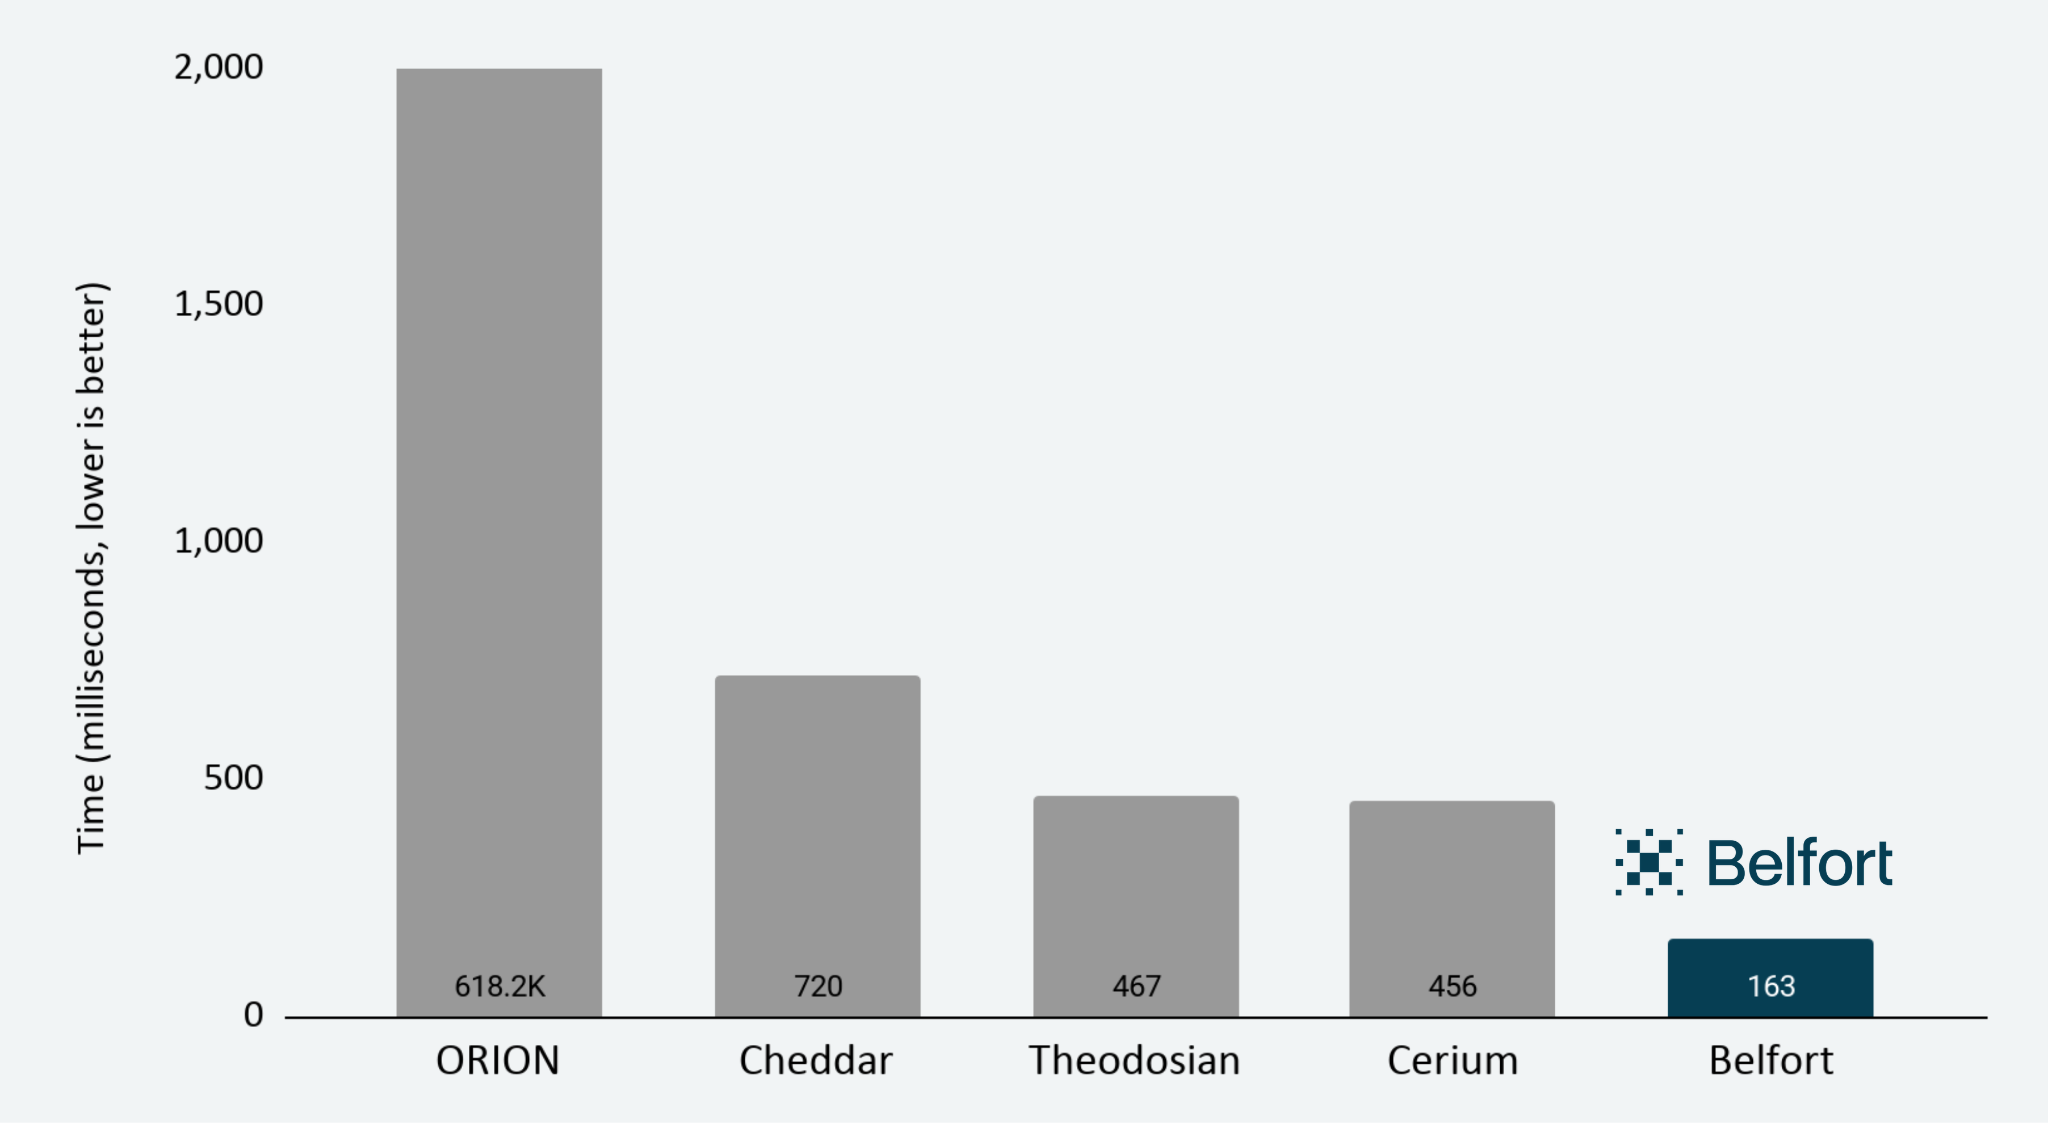
When AlexNet was trained and run on GPUs in 2012, it proved that hardware had finally caught up to the ambition of neural networks, and that one result unlocked the decade of AI that followed. Encrypted AI is at the same inflection point. Running ResNet-20 under encryption in 163ms might be our AlexNet moment: the signal that encrypted computing has crossed from theoretically possible to practically useful, and the foothold for the larger models coming next. Try it live at sofar.belfortlabs.cloud.
These significant speed-ups come without any impact on the accuracy of the underlying AI model, the model accuracy of 92.5% matches that of the non-encrypted model (92.8%). Machine learning engineers can now focus on accuracy and assume the performance is taken care of.
Performance-Enabled Accessibility
Belfort's image classification is built on top of its upcoming GPU library, Cyclops. It comes with several optimizations that make Cyclops extremely fast on Encrypted AI workloads. This performance increase translates to many other similar machine learning algorithms too. As Belfort’s CTO Michiel Van Beirendonck states: “Two years ago, running an AI model under encryption was out of reach. Cyclops closes that gap, and it's the same gap we'll keep closing as the models get bigger. This is the start of a trajectory, not the finish line.”
Two years ago, running an AI model under encryption was out of reach.
— Michiel Van Beirendonck, Belfort Co-Founder & CTO
Beyond performance, we are working with Google on their HEIR compiler, to make encrypted computing as easy as possible. “Running encrypted AI workloads not only requires performance, but also the tooling to adapt the models and tweak the performance”, says Alexander Viand, Senior Software Engineer at Belfort. Future releases will not only bring increases in performance, but also an extended feature set to make it easy to use.
What’s next and availability
This Resnet-20 demo is one step in a larger effort to make encrypted AI fast enough for real use. The work behind Cyclops carries over to other models, and that's where we're headed next: bigger networks, broader model support, and better tooling to make encrypted workloads easier to run.
Cyclops is currently in alpha with early partners. Organizations interested in testing encrypted AI on their own workloads can reach out for early access.
About Belfort
At Belfort, we believe that in an AI-first world, trust is all you need and the future of computing is encrypted. Belfort enables that vision by accelerating Encrypted Compute to make it practical at scale, ensuring that sensitive data can be processed without ever being decrypted. A spin-off from KU Leuven’s world-renowned COSIC lab, Belfort combines breakthroughs in hardware and algorithms to build the next layer of secure computing. The company has offices in San Francisco, USA, and Leuven, Belgium. https://belfortlabs.com/
Belfort releases fastest Encrypted Image Classifier available
Belfort released their demo of an encrypted implementation of ResNet-20, a popular model for image classification. It outperforms recent SOTA by 3x with a total latency of less than 200ms.